MAG B850 TOMAHAWK MAX WIFI + Ryzen 7 9800X3D + RTX 3070 Ti - nvlddmkm Event ID 153 / GPU timeout

alsi496

New member
Joined
Sep 29, 2026
Messages
22
Hello

I am experiencing intermittent GPU-related system instability on my MSI MAG B850 TOMAHAWK MAX WIFI motherboard.

My system configuration:

  • Motherboard: MSI MAG B850 TOMAHAWK MAX WIFI (MS-7E62)
  • CPU: AMD Ryzen 7 9800X3D
  • GPU: Palit GeForce RTX 3070 Ti GamingPro
  • PSU: DeepCool PQ850M 850W
  • RAM: DDR5 32GB, currently running at JEDEC 4800 MT/s (EXPO disabled)
  • BIOS versions tested:
    • Previous BIOS: E7E62AMSI.2A62
    • Current BIOS: 7E62v2A64
Problem description:

During gaming (mainly World of Warcraft, but also observed in other situations), the system occasionally experiences a GPU timeout:

  • The image freezes for several seconds.
  • Sometimes the screen briefly disappears and recovers.
  • Sometimes the GPU driver recovers automatically and the system continues working.
  • In more severe cases, the system requires a restart.
After recovery, Windows Event Viewer shows:

  • Source: nvlddmkm
  • Event ID: 153
  • Message:
    • \Device\Video3
    • Error occurred on GPUID: 100
There are no WHEA errors.
CPU and memory stability tests pass.
GPU temperature is normal.
VRAM tests pass.

Troubleshooting already performed:

  1. Clean NVIDIA driver installation using DDU.
  2. Different NVIDIA driver versions tested.
  3. EXPO disabled.
  4. RAM tested at default JEDEC 4800 MT/s.
  5. GPU tested in another PCIe slot:
    • Secondary PCIe slot
    • PCIe Gen3 mode
    • Power Limit reduced to 80%
  6. Main PCIe slot tested with:
    • PCIe Gen4 forced manually instead of Auto.
    • ASPM disabled.
  7. NVIDIA Control Panel:
    • Power management mode set to “Prefer maximum performance”.
  8. CPU NB/SoC Voltage was tested manually at 1.25V.
  9. GPU power connection verified:
    • Two separate PCIe power cables from PSU to GPU.
None of these changes completely eliminated the issue.

After updating BIOS to 7E62v2A64, I tested the system with completely default BIOS settings:

  • PCIe settings Auto.
  • EXPO disabled.
  • RAM 4800 MT/s.
The system appears more stable so far, but I need to confirm long-term stability.

My questions:

  1. Are there any known PCIe compatibility issues between MSI B850 motherboards and older PCIe 4.0 NVIDIA GPUs such as RTX 30 series?
  2. Does BIOS 7E62v2A64 contain any PCIe/AGESA fixes related to GPU link stability, PCIe power states, or nvlddmkm recovery errors?
  3. Are there recommended BIOS settings for this motherboard when using RTX 30 series GPUs?
  4. Could this behavior be related to PCIe link training, ASPM, CPU I/O/SoC behavior, or AGESA firmware?
  5. Are there any diagnostic logs or tests you recommend to determine whether the motherboard PCIe subsystem or the GPU is responsible?
I would appreciate any guidance or information about known issues with this platform combination.

Thank you.
 
If the GPU is fine then your other questions would more likely need some consideration.


1. The AMD AGESA firmware / board does have issues and you will see that the older BIOSes contain some notes.
2. AGESA 1.3.0.1d does contain changes to the Link training behaviour
3. Yes
4. Hwinfo check the PEX counters, all should show 0 excluding the recovery counter <this one changes when the lanes switch state but if the GPU remains under a constant load it shouldn't change much.

Consider downgrading the AGESA firmware, based on the release notes I would be inclined to go with BIOS 7E62v2A53
Thanks for the explanation, that’s helpful.

One thing I’m still trying to understand: when MSI releases a newer BIOS, aren’t the fixes and compatibility improvements from older BIOS versions normally carried forward into the newer versions?

In other words, if 7E62v2A53 contained PCIe-related fixes, shouldn’t those improvements also be present in 7E62v2A64 unless something was changed again later?

I’m just trying to understand whether downgrading to 7E62v2A53 can realistically behave differently from 7E62v2A64 in terms of PCIe / Link Training.
 
Update: the issue happened again.

I was testing the system with the following changes:

  • BIOS 7E62v2A64 at default/Auto settings
  • EXPO disabled, RAM at JEDEC 4800 MT/s
  • GPU Core Clock -150 MHz
  • NVIDIA Virtual Audio Device disabled
  • HAGS disabled
Unfortunately, the exact same freeze/recovery happened again and Event Viewer recorded nvlddmkm Event ID 153.

So the -150 MHz Core Clock test and disabling the NVIDIA audio device did not solve the problem.

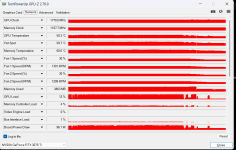
This time I had HWiNFO and GPU-Z running, so I was able to check the PCIe state immediately after the event.

GPU-Z still showed:

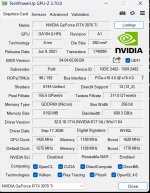
PCIe x16 4.0 @ x16 4.0

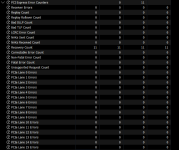
HWiNFO PEX counters immediately after the freeze:

Recovery Count increased from 10 to 11.

All other counters remained at 0:

Receiver Errors, Replay Count, Replay Rollover, Bad DLLP, Bad TLP, LCRC, NAKs Sent/Received, Correctable Errors, Non-Fatal Errors, Fatal Errors and PCIe Lane 0–15 Errors.

So at least from the counters I can see, there was no obvious PCIe transmission error recorded during the nvlddmkm 153 event, only one additional Recovery event.

I also have HWiNFO and GPU-Z sensor logs from this session and can upload them if useful.

At this point I am still trying to understand whether this points more toward the GPU itself, AGESA/PCIe Link Training, or some other interaction between the GPU and the new AM5/B850 platform.

Any thoughts on what would be the most useful next test?
 

Attachments

  • 1.png
    1.png
    64 KB · Views: 56
  • 2.png
    2.png
    51.7 KB · Views: 50
  • 3.png
    3.png
    55.4 KB · Views: 48
  • GPU-Z Sensor Log.txt
    GPU-Z Sensor Log.txt
    1.3 MB · Views: 64
Additional update with log analysis

I also uploaded both the GPU-Z sensor log and HWiNFO sensor log to the paid version of ChatGPT and asked it to correlate the data around the exact freeze.
I understand that AI analysis is not definitive, so I am sharing the actual observations from the logs in case they are useful to someone here.

The freeze appears very clearly in the logs at approximately 23:09:49–23:09:57.

Immediately before the freeze, the GPU was under high load. Then there was a sudden abnormal transition:

  • GPU load was around 97–100%
  • board power was around 240–250 W shortly before the event
  • then Memory Controller Load dropped to 0%
  • Bus Interface Load dropped to 0%
  • board power dropped to roughly 94–95 W
  • after that there is an approximately 8-second gap in the GPU-Z log
When logging resumes:

  • GPU-Z initially cannot read GPU / Hot Spot / Memory temperatures
  • GPU load is only about 1%
  • VRAM usage drops sharply from about 7658 MB to 2808 MB
  • a few seconds later the GPU starts operating normally again
This looks consistent with the GPU / driver becoming unresponsive and then being reset/reinitialized by Windows (TDR), rather than a normal performance drop. GPU-Z Sensor Log

I also reviewed the HWiNFO PCIe / PEX counters from the same session.

During the event:

  • Receiver Errors: 0
  • Replay Count: 0
  • Bad DLLP / Bad TLP: 0
  • LCRC Errors: 0
  • NAKs: 0
  • Correctable Errors: 0
  • Non-Fatal Errors: 0
  • Fatal Errors: 0
  • PCIe Lane 0–15 Errors: all 0
Recovery Count was already 11 before the freeze and remained 11, so it did not increase during this event.

After recovery, GPU-Z still showed:

PCIe x16 4.0 @ x16 4.0

Also, there was no obvious overheating:

  • GPU temperature was well below the thermal limit
  • Hot Spot and VRAM temperatures were also within normal range
There was also no obvious sustained voltage collapse visible in the sensor logs.

So at least from these logs, I do not see clear evidence of:

  • overheating
  • a PCIe lane / packet error
  • a permanent PCIe link downgrade
  • or a simple GPU core instability, since the issue also occurred with -150 MHz Core Clock
This still does not exclude the GPU itself, PSU transients, AGESA / PCIe Link Training behavior, or a driver/platform interaction.

If anyone here has experience interpreting this type of nvlddmkm Event ID 153 / TDR pattern, I would really appreciate your opinion.
I can also upload the raw GPU-Z and HWiNFO logs if that would help.
 
If the BIOS contains a fix to resolve an issue this usually carries over but there is only so much that can be done if it is the AGESA updates that are the main source of the problem. Plus if a problem is patched but then a new AGESA comes out unless people start reporting issues again it will go unnoticed, especially if most people have moved on to newer hardware / GPUs.

The PEX stats are good so it's unlikely to be a signally issue within the PCI-E Bus.

One aspect of downclocking the GPU using MSI afterburner is that this is based on the V/F curve so it's more of an offset instead of a direct -150MHz off the boost clock. What I mean by this is the boost clock is variable and based on GPU load / power and temperatures so if for example it's within the limits the boost algorithm can still run the core quite high and to max boost at times. If you want to test the GPU boost clock / if this is unstable at peak boost (for a given load) then you should go for a limit in place of an offset. EG, this is something to rule out the GPU as at times what can occur is the GPU only crashes for a specific load / voltage @specific frequency.

Open a command prompt in admin mode and type the following
nvidia-smi -lgc 210,1500

This will physically limit the maximum boost to 1500MHz (check in Hwinfo to confirm) so it does not impact the V/F curve, if the GPU is stable under this condition then it would be GPU related. I would imagine 1500MHz to be reasonable but if you wanted to go down the extreme route just to totally rule this out go lower than 1500MHz.

This is a soft setting so will reset on reboot or if you type
nvidia-smi -rgc
Thanks, that makes sense and is very helpful.

For now I have returned the GPU completely to stock settings and disabled the Ryzen iGPU in BIOS. In Windows, only the RTX 3070 Ti is now visible under Display Adapters, so I am currently testing the system in this configuration without changing anything else.

My next step was going to be either:

  • downgrade to BIOS 7E62v2A53, or
  • try the hard GPU clock limit you suggested with nvidia-smi, rather than using an Afterburner offset.
I will probably try your clock-limit method before making too many other changes, because I agree it is a cleaner way to test whether the issue is related to a specific boost clock / voltage point.

Just to remind you of one important part of the history: this same RTX 3070 Ti and the same PSU were stable on my previous Intel i7-8700K + ASUS motherboard system. I replaced the motherboard and CPU with the current MSI B850 + Ryzen 7 9800X3D, installed Windows clean, and the first freezes / nvlddmkm Event ID 153 problems started that same evening.

So this is why I am still very interested in the possibility of a platform / BIOS / AGESA interaction, although of course I understand the GPU itself still cannot be completely ruled out.

Thanks again for the detailed explanation and the nvidia-smi suggestion.
 
When I upgraded my system to the current one it worked after I figured out training just took a long time the first boot. But I had to update the bios to the december 2024 one to get decent booting times. Soon after that the january 2025 bios came and improved alot for me. I kept that a while and then went with the june 2025 bios. that gave M.1_4 detection problems so my second nvme drive wasn't detected anymore, soon after they updated that one and it became an on/off switch every reboot for that drive. So I went back to that january version since that worked fine albeit needing between 1 and 2 minutes for a soft reboot. Eventually there came a version that worked and gave decent posting times and no detection problems. So while older working settings in bios should migrate to the newer one, this isn't always the case, and trying an older version might just do the trick.
Also, I have a RTX3080 which I kept from the previous intel system and did not have any issues with it like you do. So yes, while your card appeared to work fine in the previous configuration, it could be faulty in the new one. Something you already keep in mind. When you've exhausted all options you should try it in a different system if possible to rule it out.
 
Update: Disabling iGPU did not solve the issue

I tested the suggestion from @jamarrb103 and disabled the Ryzen iGPU in BIOS.

Current test configuration:

  • MSI MAG B850 TOMAHAWK MAX WIFI
  • Ryzen 7 9800X3D
  • RTX 3070 Ti
  • BIOS 7E62v2A64
  • EXPO disabled
  • RAM running at JEDEC 4800 MT/s
  • iGPU disabled in BIOS (AMD Radeon Graphics no longer appears in Device Manager)
  • MSI Afterburner reset to stock settings and closed
Unfortunately, the issue happened again.

I got the same behavior as before:

  • short freeze (a few seconds)
  • system recovered afterwards
  • Event Viewer shows the same nvlddmkm Event ID 153 errors
This time it happened while:

  • World of Warcraft was running
  • Dota 2 was running in the background
  • I was only browsing at that moment
So it was not a heavy GPU load scenario.

I also captured HWiNFO and GPU-Z logs again around the event.

At this point, disabling iGPU does not appear to change the behavior.

Next tests I am considering:

  • testing the fixed GPU clock limit with nvidia-smi -lgc 210,1500 (as suggested above) instead of an Afterburner offset;
  • trying an older BIOS version (possibly 7E62v2A53) to compare AGESA/PCIe behavior.
Thanks everyone for the suggestions. I will continue testing and update the thread.
 
Apologies, I didn't have time to read through entire thread, so this may already have been covered. But if not, I would recommend reseating the GPU and reseating the power cables (or even replacing). I was getting same problem with my new 5070 every couple of weeks and after troubleshooting on the Nvidia support forums, I was advised to replace the power cable, which I was a bit sceptical would work, but it did. I replaced a 12V-2x6 cable with the 12VHPWR cable that came with the Seasonic PSU. Thread here:
https://www.nvidia.com/en-us/geforce/forums/user/1390349//586075//?comment=3621379
Thanks, that's a good point.
The GPU has already been reseated several times because I also tested it in the secondary PCIe slot, and it is powered by two separate PCIe cables from the PSU.
However, I have not yet tried replacing the actual PCIe power cables, so I will keep that as another test if the current GPU clock-limit test does not help.
The same GPU and PSU were stable in my previous i7-8700K + ASUS system, but the cables were of course reconnected when I rebuilt the PC, so it is still worth checking.
 
Update: hard GPU clock limit to 1500 MHz did not help

I tested the suggestion to hard-limit the RTX 3070 Ti clock using:

nvidia-smi -lgc 210,1500

The limit was applied correctly, and GPU-Z confirmed that the GPU was actually running at a maximum of 1500 MHz during the test.

Unfortunately, the same issue happened again:

  • short system/display freeze;
  • recovery after a few seconds;
  • same nvlddmkm Event ID 153 errors.
This time I also captured GPU-Z and HWiNFO logs during the event.

Just before the freeze, the GPU was still running at exactly 1500 MHz. In the GPU-Z log there is then an approximately 10-second gap, after which GPU-related activity drops sharply and VRAM usage falls from about 7.6 GB to about 2.4 GB, which again looks like a GPU/driver reset. GPU-Z Sensor Log1

HWiNFO did not show any obvious PCIe errors during the event:

  • Receiver Errors: 0
  • LCRC: 0
  • Correctable Errors: 0
  • Non-Fatal Errors: 0
  • Fatal Errors: 0
  • WHEA: 0
  • Recovery Count did not increase during the event
  • PCIe link remained at 16.0 GT/s
So at this point, disabling the iGPU did not help, and hard-limiting the GPU to 1500 MHz also did not help.

Because of that, I am now going to try BIOS 7E62v2A53 as the next isolated test, while keeping the rest of the configuration unchanged as much as possible.

I will report back with the result.
 
Update: BIOS 7E62v2A53 also did not resolve the issue. I flashed 2A53, left the BIOS completely at default settings, and the same nvlddmkm errors occurred again shortly afterwards at 05:53:48, 05:53:50 and 05:53:52.

At this point, I’m honestly getting very discouraged. I have spent a huge amount of time troubleshooting this issue, testing different BIOS versions, PCIe settings, drivers, GPU clock limits, disabling the iGPU, and many other suggestions, but the problem still remains. I’m really starting to regret choosing an MSI motherboard for this build.
 
Try an older Nvidia driver, sometimes the newest one is buggy.
Thanks. I have already tested multiple NVIDIA driver versions using DDU and clean installations. Unfortunately, the issue occurred on older drivers as well, so it does not appear to be limited to the latest NVIDIA driver.
 
For clarity, here is a complete summary of what I have already tested so far.

System / background​

  • MSI MAG B850 TOMAHAWK MAX WIFI
  • Ryzen 7 9800X3D
  • Palit RTX 3070 Ti GamingPro
  • DeepCool PQ850M 850W
  • 32 GB DDR5
  • Windows 11 clean install after changing motherboard and CPU
  • The same RTX 3070 Ti and the same PSU were stable in my previous Intel i7-8700K + ASUS system
  • The problem started after moving to the MSI B850 + Ryzen 7 9800X3D platform
  • Main recurring error: nvlddmkm, Event ID 153, GPUID: 100
  • No WHEA errors have been observed

NVIDIA / Windows troubleshooting​

  • DDU used
  • NVIDIA driver installed cleanly afterwards
  • Multiple NVIDIA driver versions tested
  • Older drivers also tested
  • HAGS disabled
  • NVIDIA Control Panel set to Prefer Maximum Performance
  • NVIDIA Virtual Audio Device disabled as a test
  • Steam Overlay disabled
  • Clean Windows installation already performed

RAM / CPU​

  • EXPO disabled
  • RAM running at JEDEC 4800 MT/s during troubleshooting
  • MemTest86: 4 passes, 0 errors
  • OCCT CPU + RAM test: no errors
  • SoC voltage on Auto tested
  • SoC override around 1.25 V also tested
  • No improvement

GPU stress / stability tests​

  • OCCT 3D Adaptive Heavy tested
  • OCCT VRAM tested
  • VRAM test also previously run for around one hour
  • No OCCT errors
  • GPU temperatures normal
  • Hotspot temperatures normal
  • VRAM temperatures normal
  • No overheating observed during failures

GPU clock / power testing​

  • GPU Core -100 MHz tested
  • GPU Core -150 MHz tested
  • Power Limit 80% tested
  • GPU returned to completely stock settings afterwards
  • MSI Afterburner reset and closed
  • Hard GPU clock limit tested with:
nvidia-smi -lgc 210,1500

  • The command applied correctly
  • GPU-Z confirmed that the RTX 3070 Ti was actually running at a maximum of 1500 MHz
  • The same nvlddmkm Event ID 153 still occurred even with the hard 1500 MHz limit
  • So simply reducing GPU boost frequency did not solve the problem

PCIe testing​

  • GPU tested in the main/top PCIe slot
  • GPU tested in the secondary/lower PCIe slot
  • PCIe Gen3 tested in the lower slot
  • PCIe Gen4 forced in the main slot
  • PCIe Auto tested
  • CPU PCIe ASPM disabled
  • None of these changes solved the problem
  • GPU-Z confirms normal PCIe x16 4.0 @ x16 4.0 operation under load

PCIe error monitoring​

HWiNFO PCIe counters were monitored during actual failures.

The following remained at 0:

  • Receiver Errors
  • Replay errors
  • Replay rollover
  • Bad DLLP
  • Bad TLP
  • LCRC errors
  • NAK errors
  • Correctable errors
  • Non-Fatal errors
  • Fatal errors
  • PCIe lane errors
  • PCIe link speed remained at 16.0 GT/s
  • Recovery Count did not increase during the captured failure
  • WHEA remained at 0

iGPU test​

  • Ryzen 9800X3D iGPU disabled in BIOS
  • AMD Radeon Graphics disappeared from Device Manager
  • Only the RTX 3070 Ti remained active
  • The same nvlddmkm Event ID 153 still occurred
  • So disabling the iGPU did not solve the issue

BIOS testing​

  • Older BIOS E7E62AMSI.2A62 was previously used
  • Updated to BIOS 7E62v2A64
  • BIOS defaults tested
  • EXPO disabled
  • Problem still occurred
  • Downgraded from 7E62v2A64 to 7E62v2A53
  • BIOS 2A53 tested completely at default settings
  • The same nvlddmkm errors occurred again shortly afterwards
  • Therefore BIOS 2A53 did not solve the problem either
  • I have now returned to BIOS 7E62v2A64
  • I am currently testing FCH Spread Spectrum = Enabled

Power / GPU cabling​

  • GPU is powered using two separate PCIe power cables from the PSU
  • This has already been physically verified
  • The same PSU and GPU previously worked normally in my old Intel + ASUS system
  • I have not yet replaced the actual PCIe power cables with different PSU cables
  • I also have not yet tested another PSU

Logs captured during a real failure​

During one of the recent failures with the GPU hard-limited to 1500 MHz:

  • GPU was still running at exactly 1500 MHz immediately before the failure
  • GPU load was high
  • Temperatures were normal
  • Power draw was not near the normal maximum of the card
  • GPU-Z then showed an approximately 10-second logging gap
  • After the gap:
    • Memory Controller Load dropped to 0
    • Bus Interface Load dropped to 0
    • GPU power dropped sharply
    • VRAM usage dropped from around 7.6 GB to around 2.4 GB
  • This looks consistent with a GPU/driver reset and recovery
  • No obvious PCIe error counters or WHEA errors were recorded during the event

What is still not tested / still planned​

  • Reconnect both GPU PCIe power cables on both ends
  • If possible, replace both PCIe power cables with other original compatible DeepCool PQ850M cables
  • Memory Clock -200 MHz as a separate test
  • MPO disabled as a separate test
  • Another PSU
  • Another GPU
  • RTX 3070 Ti in another system, if I can get access to one
At this point I have already spent a huge amount of time testing BIOS versions, PCIe settings, GPU clocks, power limits, drivers, Windows settings, RAM, iGPU, and platform settings.

Unfortunately, the same nvlddmkm Event ID 153 keeps returning.
 
Update: I also rechecked the GPU power connections.

The RTX 3070 Ti is powered by two separate PCIe power cables from the PSU. I have already unplugged and reseated the power connectors, but unfortunately this did not change anything and the same nvlddmkm Event ID 153 issue continues.

I do not have another set of original compatible PCIe cables for the DeepCool PQ850M, so I cannot currently test replacement cables.

FCH Spread Spectrum has also been tested and did not help.

My next isolated test will be Memory Clock -200 MHz, with Core Clock at stock and Power Limit at 100%.
 
I have these identical issues on my machine:
x870 Tomahawk Wifi, R7 9800x3d, RTX 5090
the problem persists when using a 9950x3d and RTX 4090 in the same motherboard, just like others in the forums.

I have reported it as a problem in Cyberpunk2077, Runescape 3, Path of Exile, and even without a single game running.
I have tried pretty much every fix that people are talking about here related to downclocking hardware, lowering power limits, checking temperatures, replacing gpu entirely, random bios fixes, old motherboard firmware, etc.
Thanks for sharing this — your case sounds very similar to mine.

What is the current status on your side?

  • Have you found anything that actually reduced or stopped the issue?
  • What are you planning to try next?
  • At what point are you in the troubleshooting process now?
  • Since you already tested different CPUs and GPUs on the same motherboard, do you currently suspect the motherboard / BIOS / AM5 platform itself?
  • Is there anything from your own testing that you would recommend I try next?
I’m especially interested in whether you found any test that clearly changed the behavior, even temporarily.
 
Another important update: the same nvlddmkm Event ID 153 has now occurred while I was only using a web browser, with no games running. So the issue is clearly not limited to heavy GPU load or running multiple games at the same time.
 
Another important update: the same nvlddmkm Event ID 153 has now occurred while I was only using a web browser, with no games running. So the issue is clearly not limited to heavy GPU load or running multiple games at the same time.
Maybe your GPU is dying. Have you tried with the igpu? You can remove the 3070ti and use the igpu, see if it happens with that also. Because at this point it's either the GPU or the PCIe slot.
 
Back
Top